01Who should do the ranking?
Every big platform already narrowed a catalogue of billions down to a page of maybe twenty items before you ever see it. What is left for an outsider is small but real: you can re-order that page, you can add a different source of signal, or you can look at the page and say what it is made of.
A browser extension is a good place to try each of these. It runs next to the platform, sees only what you see, stores things locally, and cannot touch the platform’s own model. That limit is useful. It forces each project to be honest about which part of recommendation it is actually doing.
| Extension | Stance | Where the candidates come from | What it changes |
|---|---|---|---|
| RecoLens | Second opinion | YouTube’s own “up next” rail | Shows a re-ranked copy beside YouTube’s. The page itself is untouched. |
| SpotRecs | Outside signal | Last.fm (similar tracks, similar artists, tags) plus YouTube’s sidebar | Builds its own queue and plays it on YouTube. |
| Netflix Lens | Read-only X-ray | The titles already on your Netflix page | Nothing. It only reads and explains. |
02RecoLens: a second opinion on “Up next”
RecoLens adds a side panel to YouTube watch pages. It reads the “up next” rail, treats those videos as the candidate pool, and ranks them again through the same stages a production recommender uses. YouTube’s rail stays exactly where it was, so you can compare the two orders side by side.
Stage 1 and 2: get a pool, then cut it cheaply
A browser cannot search a billion videos, so RecoLens does not try. YouTube already did retrieval at global scale, and the rail is the pool. The five generators exist so each candidate carries a record of which strategies surfaced it. A video found by several generators is usually a better bet than one found by a single one, so that agreement becomes a feature.
The light ranker is deliberately simple. It is a weighted sum, and the weights show what I think matters most:
Intent similarity gets the largest weight: how close is this video to what you have been watching lately. The clickbait penalty is the only negative term, and it is large enough to matter. It is built from title shouting (capital-letter ratio), exclamation marks and emoji.
Stage 3 and 4: predict many things, then decide what you want
The heavy ranker predicts six different outcomes for each video instead of one “relevance” score. Clicks are a noisy signal driven by titles. Shares say more about quality. Return visits say more about channel loyalty. Keeping them separate is the point.
The value model is the part I find most worth copying. It is a separate step that turns the six predictions into one number:
Why separate it from the ranker? Retraining a model is expensive, while changing what you care about is cheap. If you want less watch time and more satisfaction, you change a weight and the slate changes immediately. In RecoLens those weights are sliders on the options page. “Quality-adjusted watch time” caps predicted watch time at the video’s own length and at one hour, then scales it by predicted completion, so one ten-hour stream cannot win by being long.
Stage 5: choose a set, not a list
Scoring videos one at a time tends to pick five near-duplicates. The re-ranker builds the slate instead:
- MMR diversity (λ = 0.7). Each next pick must score well and differ from what is already chosen.
- Per-channel cap. No channel gets more than a third of the slots.
- Exploration (ε = 0.15). From position 3 down, a pick is sometimes swapped for an outsider. The top two stay exploit-only, because that is where people click.
- Cold start. Until the extension has seen 20 events from you, exploration rises to at least 0.35.
- New-creator boost. Small channels you have not watched (under 100,000 views) get up to +0.15, scaled down by clickbait signals.
03What the RecoLens demo shows
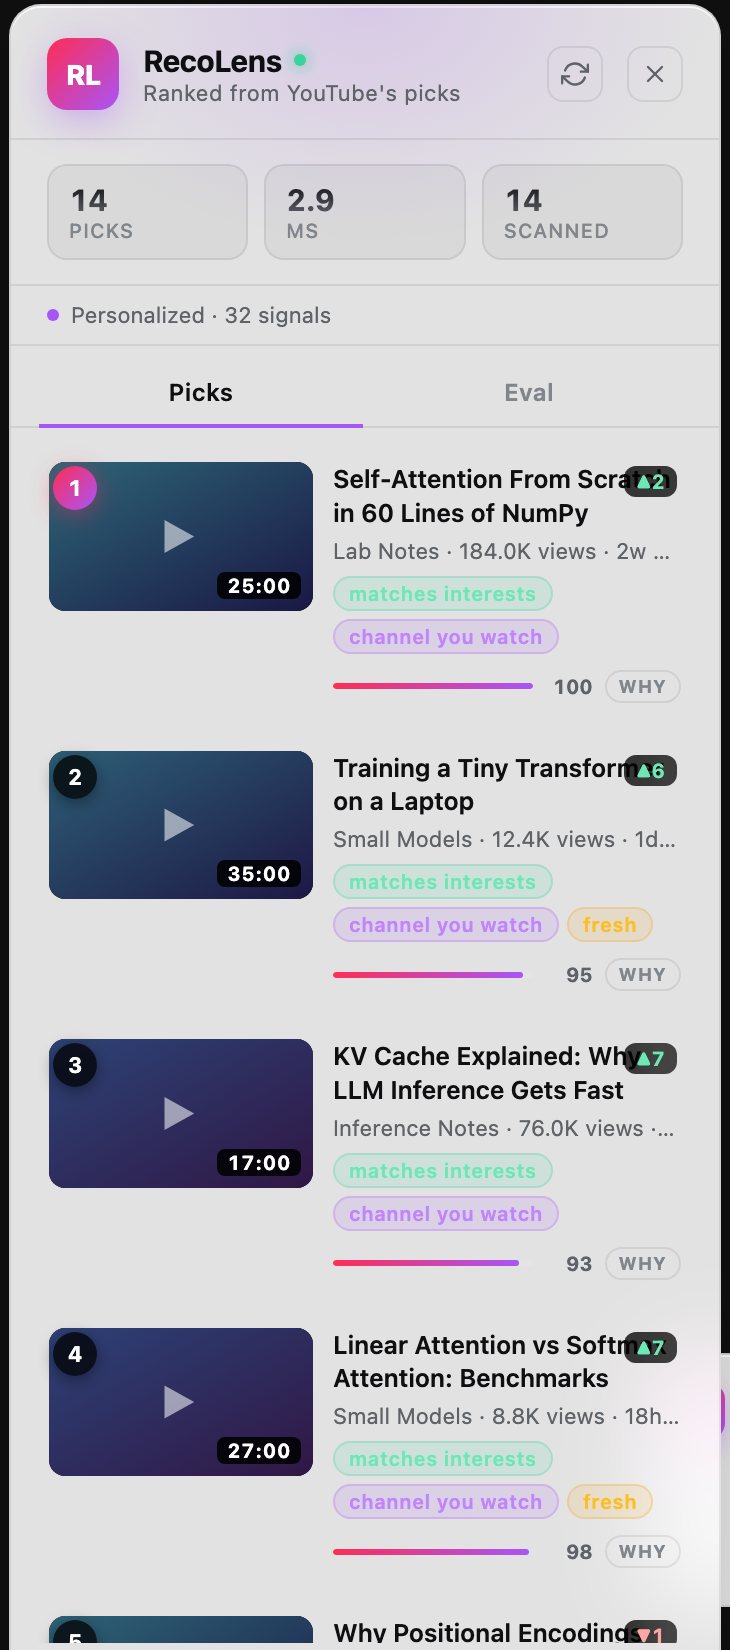
To get real output without touching my own YouTube history, I loaded the extension’s actual pipeline code in a test page with a fake chrome.storage and fed it 14 invented videos about attention in transformers, plus a few off-topic ones. I wrote YouTube’s order myself so that popular, off-topic and clickbait items sit near the top, the way a popularity-heavy rail can. The profile had eight invented watch histories repeated four times. The random seed was fixed so the screenshot and the numbers match.
| Video (invented title) | YouTube position | RecoLens position | Likely driver (my reading of the reason chips and weights) |
|---|---|---|---|
| Self-Attention From Scratch in 60 Lines of NumPy | 3 | 1 | Close to the current video and to your intent vector; a channel you watch |
| Training a Tiny Transformer on a Laptop | 8 | 2 | Matches interests; small, fresh channel |
| KV Cache Explained: Why LLM Inference Gets Fast | 10 | 3 | Matches interests; a channel in your history |
| Top 10 Gaming Moments of the Month | 5 | 11 | Far from your intent vector (intent similarity has the largest light-ranker weight) |
| 10 HOURS of Relaxing Lo-Fi Beats to Study To | 1 | 13 | Off-topic; the watch-time cap should stop its length from helping |
| YOU WON’T BELIEVE This GPU Trick!!! | 2 | 14 | Clickbait penalty on shouting, exclamation marks and emoji |
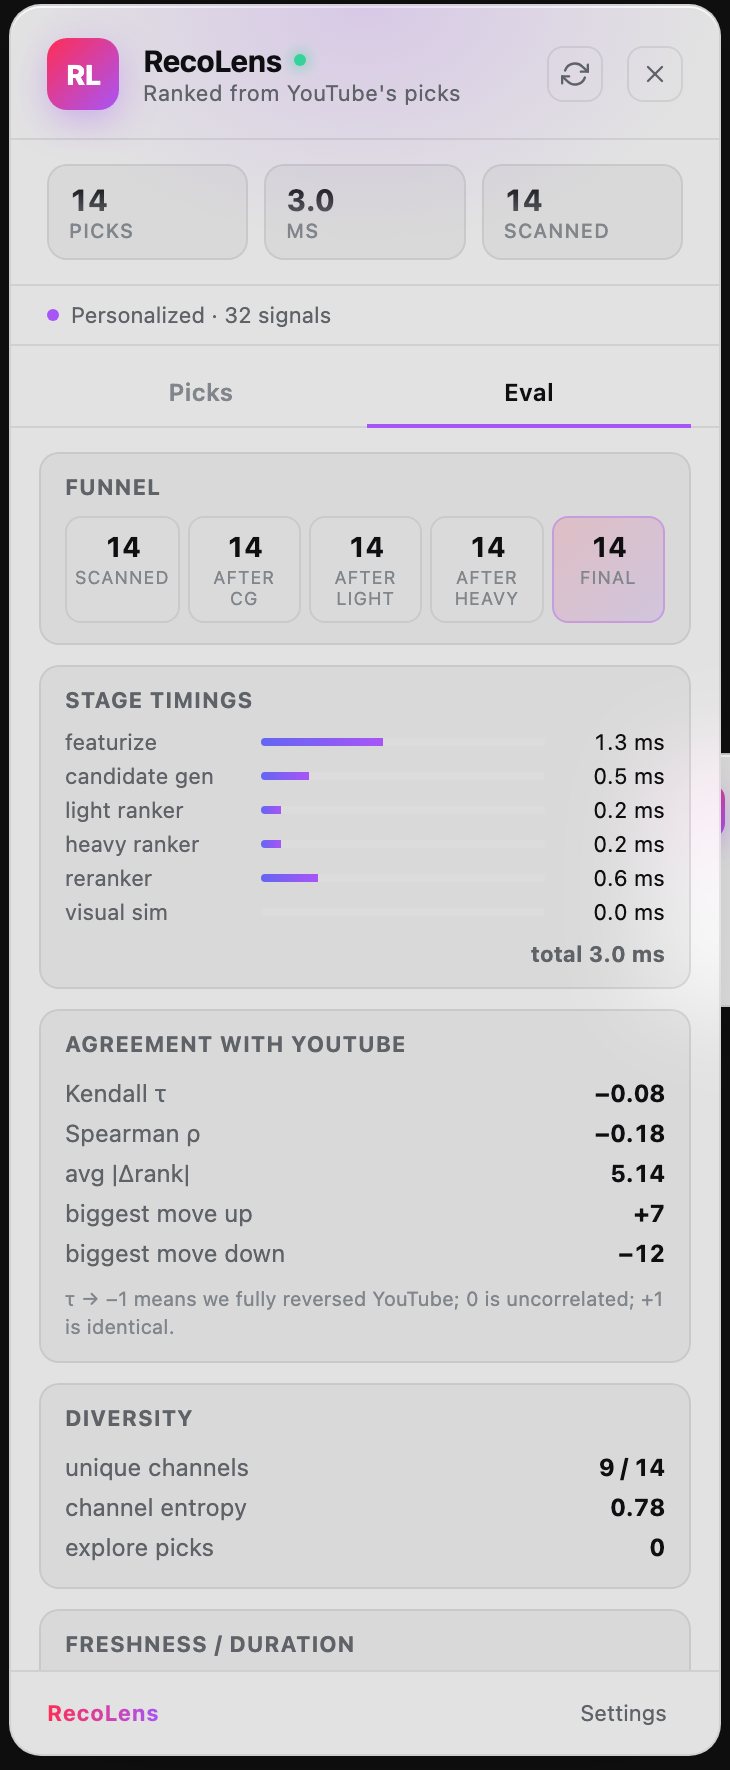
The eval tab summarises the whole slate. It processed 14 candidates in about 3 ms in headless Chrome with the optional visual-similarity step switched off, and reports how far the new order sits from YouTube’s:
Read the agreement numbers carefully
A Kendall τ near zero only says “this order is not correlated with YouTube’s.” It does not say the new order is better. I also built the input order myself, and every coefficient in the rankers is a hand-set prior, not something trained on watch logs. What the demo does show is that the stages behave as designed: topical videos rise, a shouting title and an off-topic ten-hour stream sink, and no single channel dominates.
04SpotRecs: borrowing signal for music
RecoLens has no signal of its own beyond your local history. SpotRecs goes the other way for music: it asks an external source. It detects the song you are playing on YouTube (from the structured song/artist rows, then title parsing, then channel name), and gathers candidates from six places in parallel:
- Similar tracks from Last.fm: “people who listened to X also listened to Y.” Best quality, but it can return nothing for niche tracks.
- Similar artists, taking one top track from each of six.
- Session chain: similar tracks to the last two other songs you played.
- Tag-based discovery: popular tracks under the song’s tags (for example “indie” or “90s”).
- Session tags: top tracks for the two most common tags this session.
- YouTube’s own sidebar, first five.
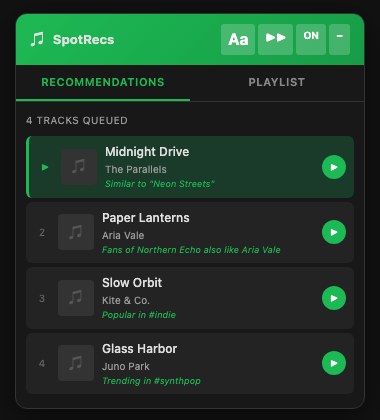
The six lists are interleaved round-robin (one from each in turn, de-duplicated) until there are 15, so no single source dominates. That handles the Last.fm gap: when the best source is empty, the others fill in. Each result carries a plain reason such as “Similar to ‘…’” or “Popular in #indie,” and the widget shows it.
Learning from thumbs, with a few explicit rules
This is small, readable personalisation, not a trained model. A thumbs-up adds to counters for the artist and the track’s tags. Then each candidate is scored:
The final order is a weighted random shuffle, not a sort. Each pick’s weight is max(1, score + remaining − index), so liked artists appear more often but you still get variety. The top 10 go to the widget. Session memory holds the last 10 tracks and 20 tags and resets after two idle hours.
05Netflix Lens: explain, don’t re-rank
Netflix Lens is the most cautious of the three. It is read-only and local: it captures the titles on your /browse page, optionally reads the ViewingActivity.csv that Netflix lets you download, and shows what it can infer. It never claims to know why Netflix chose something. Everything is labelled as inferred from observable evidence.
Page X-ray: how personal is the page?
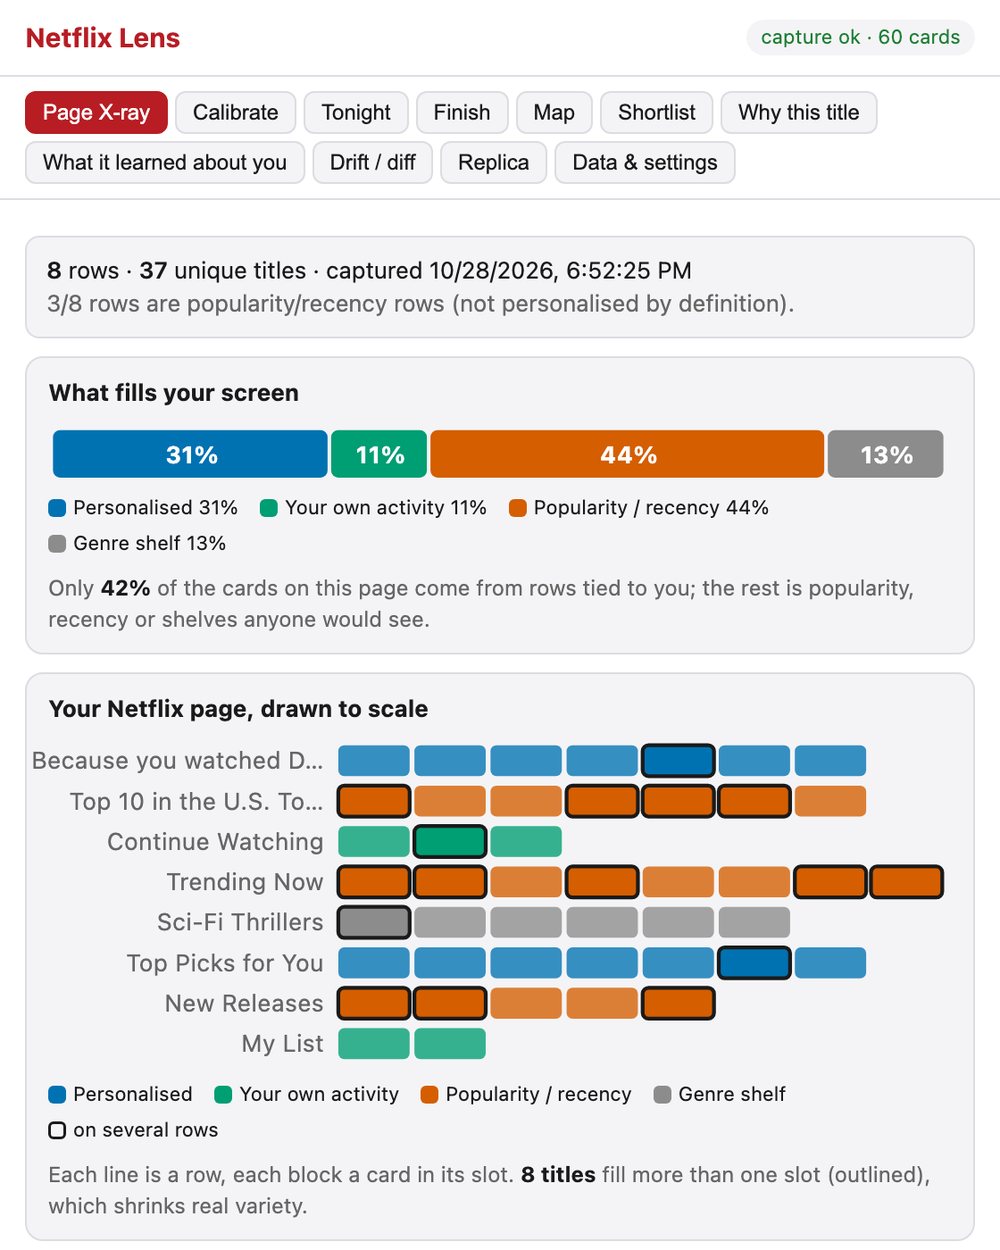
Netflix rows come in types. “Because you watched X” is tied to you. “Top 10 today” and “Trending now” are the same for many people. The X-ray colours every card by its row type, so you can see how much of the screen is personal.
Tonight: your ranking against Netflix’s
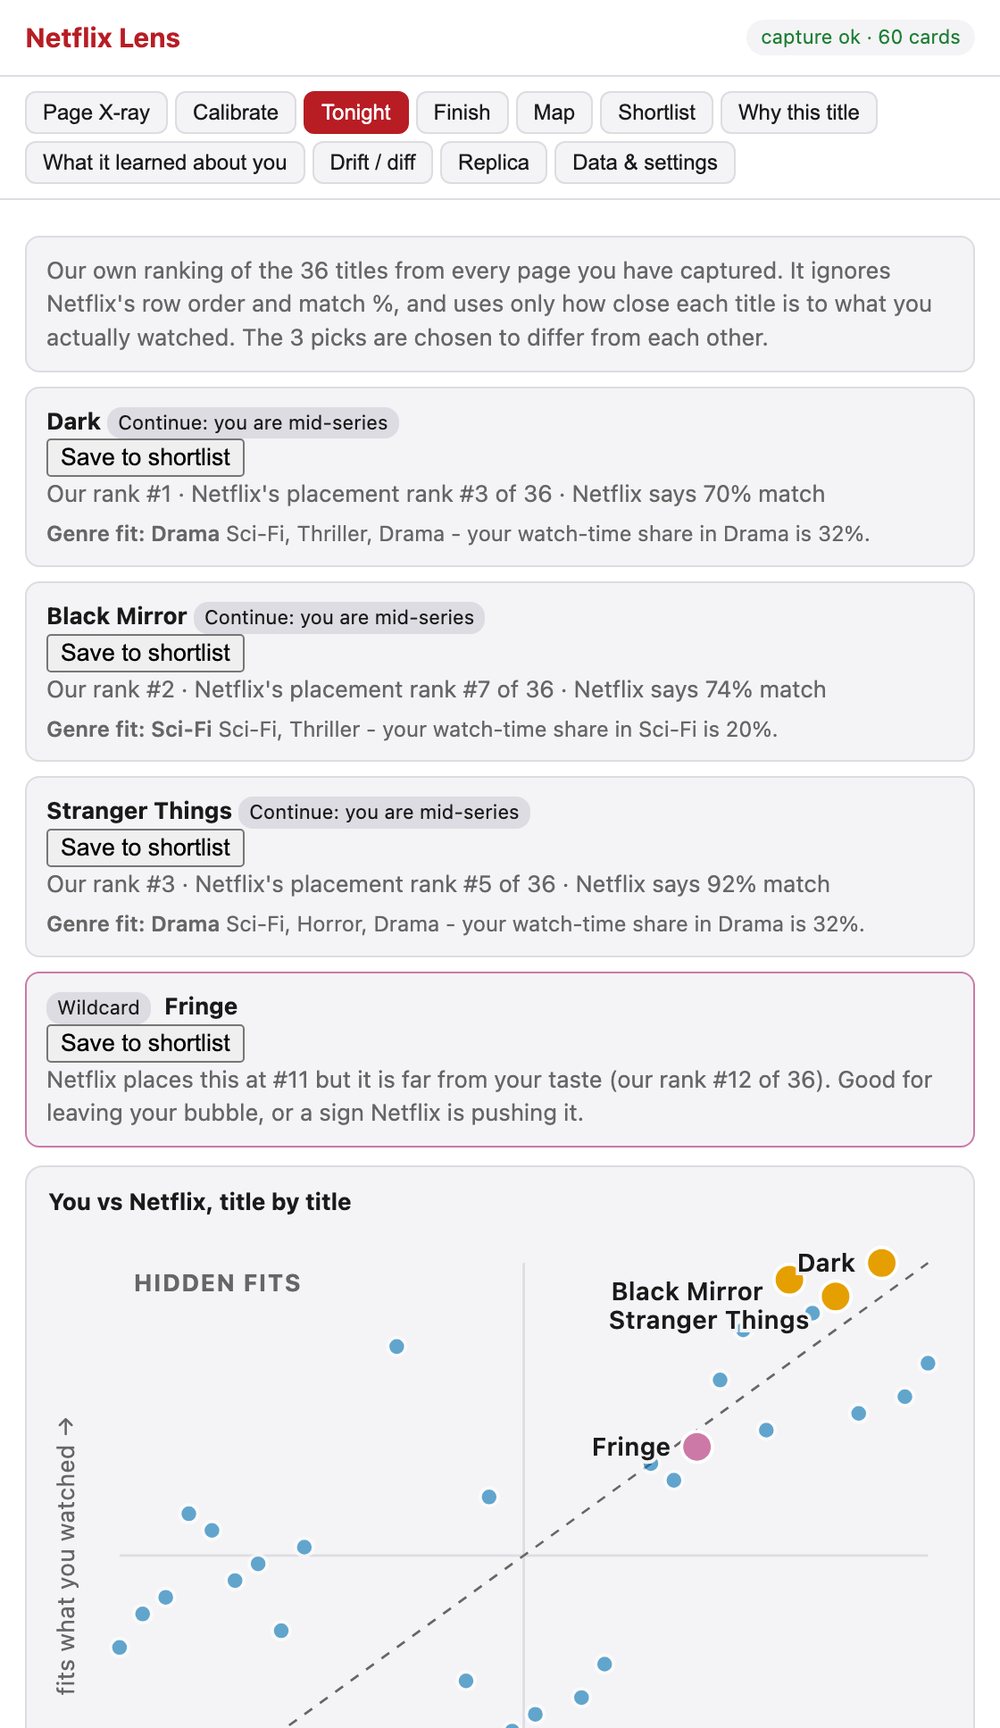
This is where it becomes a recommender. The extension ranks every title it has captured using only text similarity (TF-IDF over title, genres and synopsis) to your recency-weighted watch history, with a half-life of 120 days. It is deliberately blind to Netflix’s row order and match percentage. Those signals are kept apart, so the two rankings can be compared.
The three picks are chosen with the same MMR idea as RecoLens (λ = 0.7), so they differ from each other. Shows you are mid-series get a boost and ones you dropped get a penalty. A fourth “wildcard” is a title Netflix places high but that is far from your taste. It is either a good way out of your bubble or a sign Netflix is pushing it.
Cold start without an export
If you have not imported viewing history, a Calibrate tab lets you rate titles (Love / Fine / Already seen / Not for me), and each next title shown is the one least like what you have rated. It also builds a pseudo-history from signals that need no export: rows named “Because you watched X” prove X is in your history; Continue Watching and My List name titles you engaged with; and posters you hover on for more than a second count a little. Explicit beats implicit: Love is weighted 3, Fine and Seen 1, Continue Watching 1.2, My List 0.8, and hover time 0.12 per second up to a cap of 1.
06Four patterns that repeat
I did not plan these as a set, but the same four design choices showed up in all three.
- Separate what is predicted from what is wanted. RecoLens predicts six outcomes, then a swappable value model decides the trade-off. Netflix Lens keeps “our score” and “Netflix’s signals” apart so they can be compared. Mixing them hides the trade-off.
- Show the reason in the interface. Reason chips in RecoLens, reason lines in SpotRecs, an evidence list in Netflix Lens. A recommendation you cannot question is hard to trust or fix.
- Plan for cold start on day one. RecoLens raises exploration below 20 events, SpotRecs falls back from similar tracks to artists to tags, Netflix Lens has the Calibrate tab. Every recommender starts with no data on someone.
- Pick a set, not a list. MMR appears in RecoLens and in Netflix Lens, and SpotRecs interleaves sources and shuffles with weights. The best five by score alone are often five of the same thing.
07What is unproven
Honest limits, per project
RecoLens. Rankers are hand-weighted linear models, not trained on logged interactions. Embeddings are hashed bag-of-words, so “cat” and “kitten” do not match. The candidate pool is whatever YouTube already put on the page. YouTube’s page structure changes, so the scraper will drift. There is no A/B framework, so I have no evidence that its order is better for anyone.
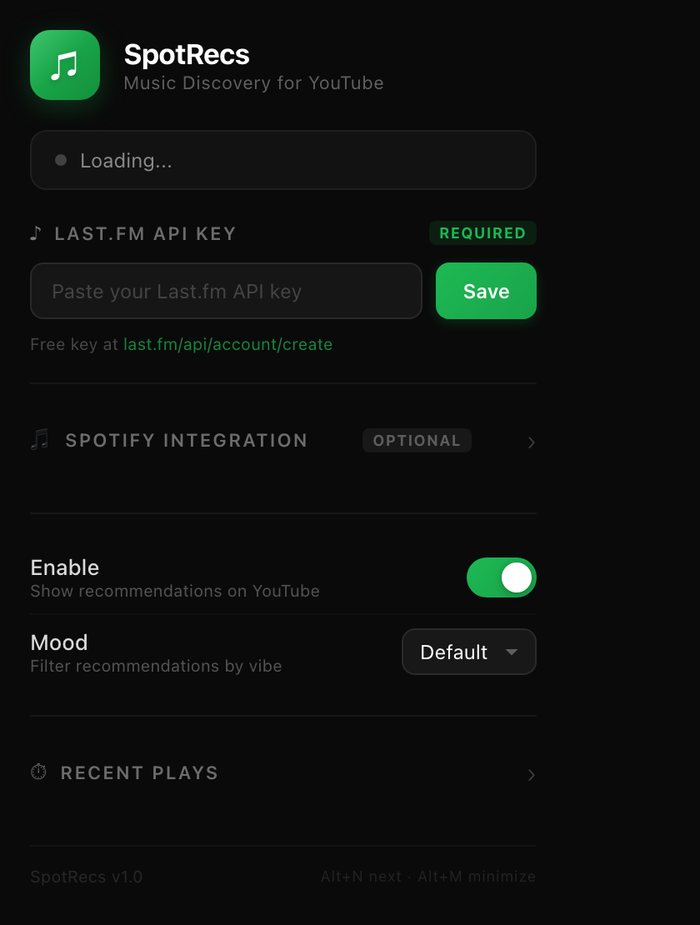
SpotRecs. It needs your own free Last.fm key. The scoring rules are hand-set counters with no offline evaluation, and there are no tests in the project yet. Quality depends on Last.fm’s similarity data, which is thin for niche tracks.
Netflix Lens. This is v0.1. Its page selectors have not been verified against the live Netflix site; the screenshots here come from a synthetic preview, not a real account. Similarity is TF-IDF text, not neural embeddings, and the planned MovieLens-trained baseline (“Replica”) is not built.
What I would build next is the missing ground truth: a small logged-interaction dataset so the hand-set weights can be replaced by trained ones, and an honest A/B on whether a re-ranked slate gets more completed watches. Until then these are working demonstrations of recommender design, not recommenders I would claim are better than the platforms’.